
[论文解读] Humanoid-Gym: Reinforcement Learning for Humanoid Robot with Zero-Shot Sim2Real Transfer
tldr: Humanoid-Gym 是一个基于 Nvidia Isaac Gym 的开源 RL 框架,训练 humanoid locomotion 策略,并实现零-shot sim-to-real 转移,具备 MuJoCo 的 sim-to-sim 验证和在两个 RobotEra 人形机器人(XBot-S 和 XBot-L)上的实地验证。
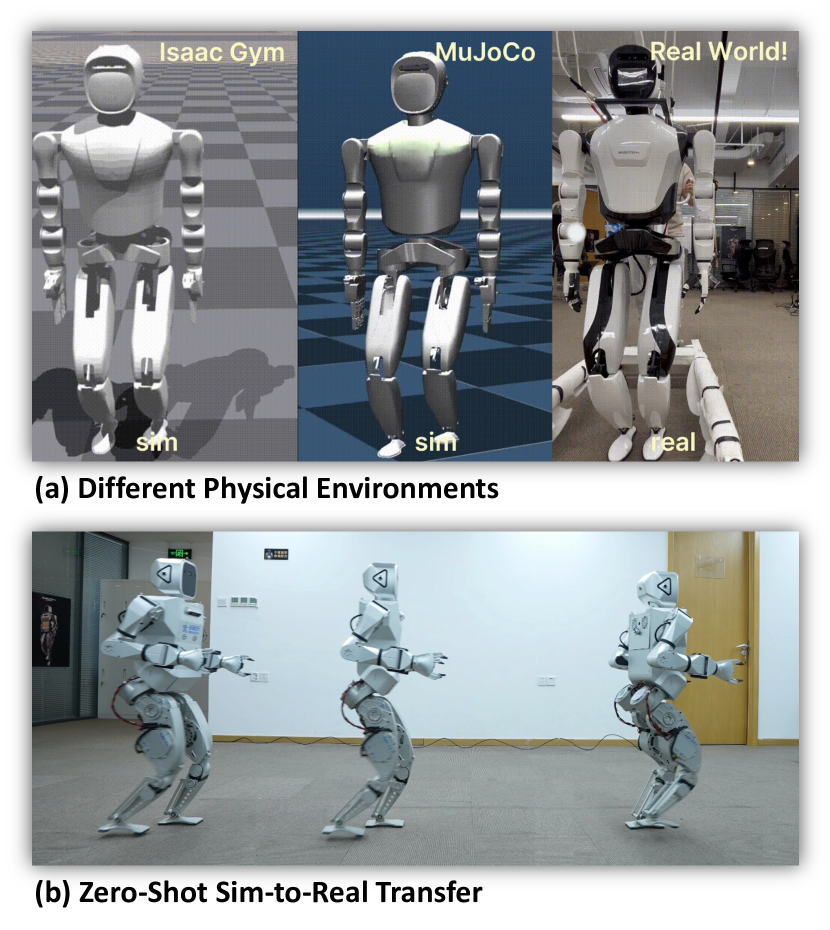
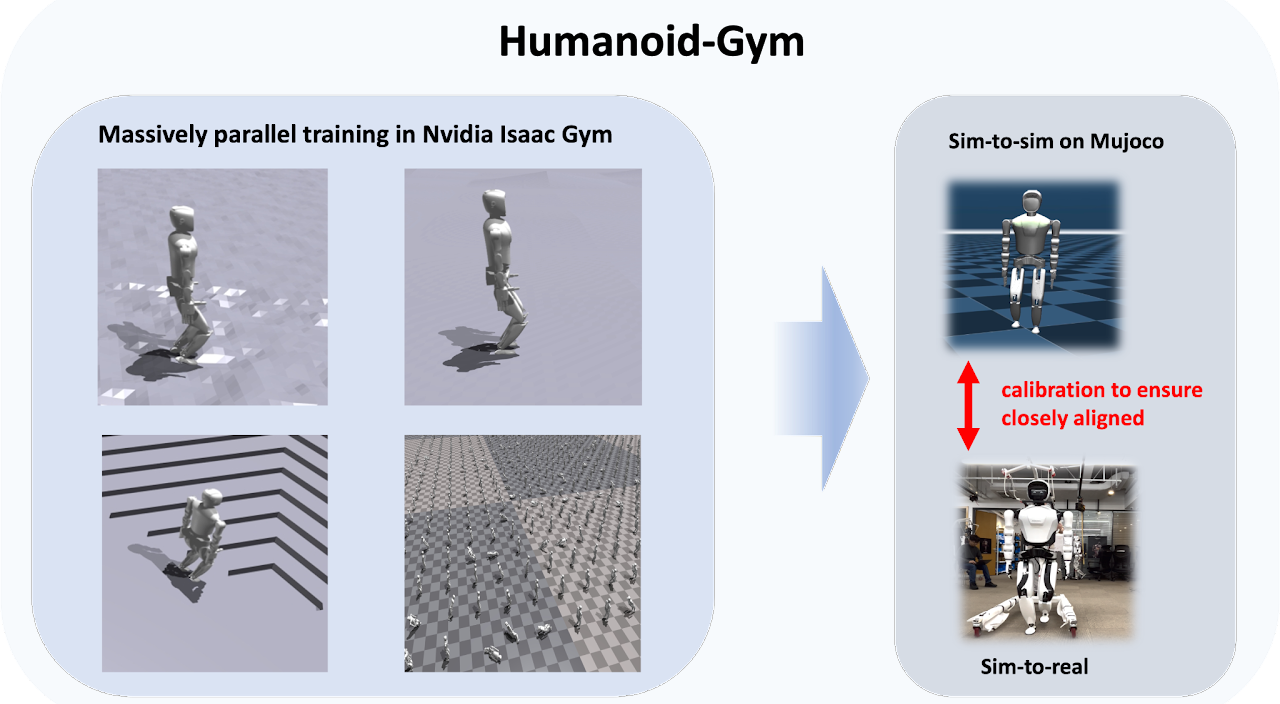
Humanoid-Gym is an easy-to-use reinforcement learning (RL) framework based on Nvidia Isaac Gym, designed to train locomotion skills for humanoid robots, emphasizing zero-shot transfer from simulation to the real-world environment. Humanoid-Gym also integrates a sim-to-sim framework from Isaac Gym to Mujoco that allows users to verify the trained policies in different physical simulations to ensure the robustness and generalization of the policies. This framework is verified by RobotEra's XBot-S (1.2-meter tall humanoid robot) and XBot-L (1.65-meter tall humanoid robot) in a real-world environment with zero-shot sim-to-real transfer. The project website and source code can be found at: https://sites.google.com/view/humanoid-gym/.
研究动机与目标
- 实现不同尺寸的人形机器人从仿真到现实世界的零-shot 转移。
- 提供一个 sim-to-sim 验证路径,以在多样化动力学条件下测试策略。
- 提供一个可访问的、开源的 RL 库,具备针对人形的专门奖励设计和领域随机化。
- 通过基于 MuJoCo 的验证,在没有实际机器人时实现鲁棒策略验证。
提出的方法
- 在部分可观测马尔可夫决策过程(POMDP)中,使用一个强化学习模型 M = <S,A,T,O,R,γ>,将观测映射到动作,策略为 π(a|o),以最大化期望回报。
- 通过 Proximal Policy Optimization (PPO) 损失进行优化,同时在训练阶段引入不对称演员-评论家和特权信息。
- 设计一个高频控制循环(策略 100 Hz;内部 PD 控制器 1000 Hz),带有参考正弦步态和用于足部接触的周期性站立掩模。
- 定义一个丰富的观测空间,包括时钟信号、指令、关节状态、角速度、基座姿态,以及特权观测,以实现鲁棒的本体感知。
- 在关节位置/速度、延迟、摩擦、马达力量、载荷等动力学特性上使用领域随机化,以弥合仿真与现实之间的差距。
- 在 Nvidia Isaac Gym 中进行广泛训练,并在尝试 sim-to-real 转移之前通过 sim-to-sim (MuJoCo) 进行验证。
- 通过校准 MuJoCo 动力学,使之与现实世界的执行器和四肢行为高度吻合,通过比较腿摆正弦波和关节相位图来验证。
实验结果
研究问题
- RQ1能否在不同尺寸的人形机器人之间实现零-shot 的仿真到现实转移?
- RQ2MuJoCo 的 sim-to-sim 验证是否提供与现实世界性能相关的可靠鲁棒性检查?
- RQ3领域随机化与奖励设计在缩小人形机器人仿真与现实之间差距方面有多有效?
- RQ4在经过校准后,MuJoCo 动力学能够多么接近真实世界的人形行走?
- RQ5对于没有物理机器人可用的研究人员,在开源部署 Humanoid-Gym 时需要考虑哪些实际因素?
主要发现
- 已经在仿真中训练的策略实现了对现实世界人形机器人(XBot-S 和 XBot-L)的零-shot 转移。
- 经过校准的 MuJoCo 动力学产生的腿摆轨迹和关节相位图与真实世界数据高度吻合,表明提高了仿真到现实的保真度。
- Humanoid-Gym 支持在不同环境动力学下进行 sim-to-sim 验证,支持策略的鲁棒性和泛化。
- 领域随机化和专门的奖励设计使仿真到现实转移场景下在平坦和不平坦地形上实现稳定的运动。
- 该框架已开源实现,包含从 Isaac Gym 训练到 MuJoCo 验证再到现实世界部署的完整管线。
阅读本论文
在 Nubint 阅读器中打开原文,边读边就任意段落提问。
在 Nubint 中阅读本论文本解读由 AI 根据论文原文生成,引用前请核对原文。