
[论文解读] LLaVA-MoLE: Sparse Mixture of LoRA Experts for Mitigating Data Conflicts in Instruction Finetuning MLLMs
引入稀疏的 LoRA 专家混合(MoLE),在对多模态大语言模型在混合领域指令数据上进行微调时缓解数据冲突,在成本相近的情况下相较于普通 LoRA 获得增益。
Instruction finetuning on a variety of image-text instruction data is the key to obtaining a versatile Multimodal Large Language Model (MLLM), and different configurations of the instruction data can lead to finetuned models with different capabilities. However, we have discovered that data conflicts are inevitable when mixing instruction data from distinct domains, which can result in performance drops for tasks of a specific domain. To address this issue, we propose to apply an efficient Mixture of Experts (MoE) design, which is a sparse Mixture of LoRA Experts (MoLE) for instruction finetuning MLLMs. Within the Transformer layers, we extend the popular Low-Rank Adaption (LoRA) method by creating a set of LoRA experts specifically for the MLP layer, and route each token to the top-1 expert based on a routing function, allowing adaptive choices for tokens from different domains. Since the LoRA experts are sparsely activated, the training and inference cost are kept roughly constant compared to the original LoRA method. By replacing the plain-LoRA of LLaVA-1.5 with our MoE design, our final model is named LLaVA-MoLE. Extensive experiments proved that LLaVA-MoLE effectively mitigates the data conflict issue when mixing multiple distinct instruction datasets with various configurations, and achieves consistent performance gains over the strong plain-LoRA baselines. Most importantly, on the mixed datasets, LLaVA-MoLE can even outperform the plain-LoRA baseline trained with twice the samples.
研究动机与目标
- 在混合不同领域数据集对指令进行微调时识别数据冲突问题。
- 提出稀疏 LoRA 专家混合(MoLE),将 token 路由到域特定的 LoRA 专家。
- 证明 MoLE 能缓解冲突并维持与普通 LoRA 相近的计算成本。
- 表明 MoLE 即使在对照组使用更多数据或训练时间时,亦能超过普通 LoRA 的基线。
提出的方法
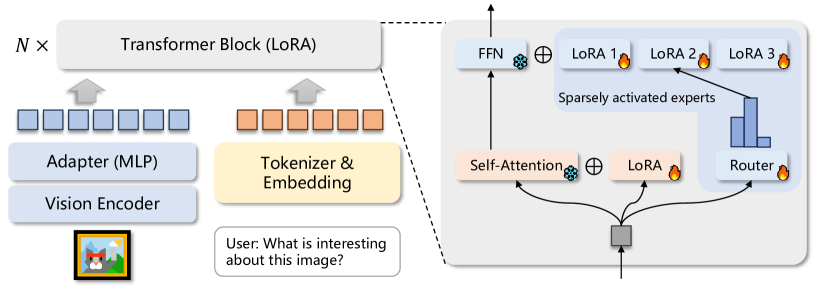
- 通过在 Transformer 结构中的每个 FFN 层增加多个 LoRA 专家来扩展 LoRA。
- 使用一个 top-1 路由器根据嵌入将每个 token 指派给一个专家,并将该专家的输出并入到 FFN。
- 在 FFN 层之间共享一个路由器,使所有层对同一 token 使用相同的专家选择。
- 引入负载均衡损失以鼓励均匀的专家利用率,防止空闲容量。
- 在多种数据配置和基准测试中比较稀疏 MoLE、密集 MoE 和普通 LoRA。
实验结果
研究问题
- RQ1在将领域多样的指令数据混合时,稀疏 MoE 路由的 LoRA 专家是否能减小性能下降?
- RQ2在不同数据配置下,MoLE 在性能和计算效率方面相对于普通 LoRA 和密集 MoE如何?
- RQ3在数据冲突下,专家数量和 LoRA 阶数对 MoLE 效能的影响?
- RQ4在跨域调整数据采样比时,MoLE 是否能实现更好的任务特定性能?
主要发现
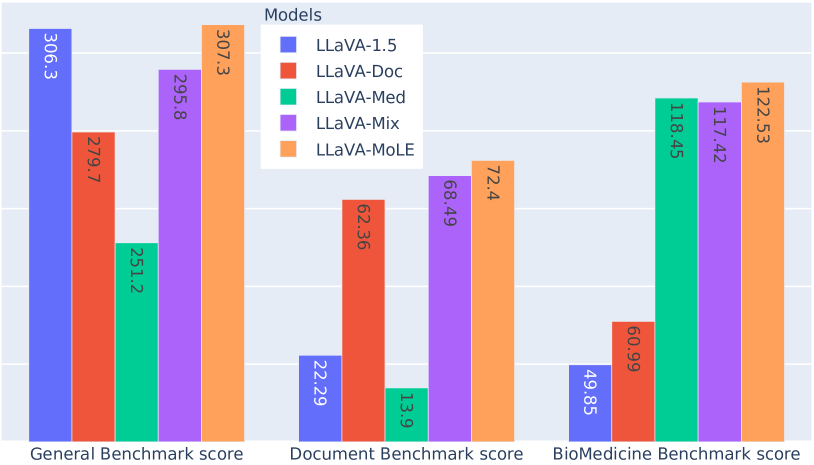
- 在混合通用、文档和生物医学指令数据时,MoLE 一直优于普通 LoRA。
- 在数据冲突下,MoLE 保持甚至超越基线性能,训练成本与普通 LoRA 相近。
- 在混合数据集上,MoLE 能超过用两倍样本训练的 Mix 基线。
- 在许多配置中,增加到 5–3 名专家通常能带来较强结果,具体取决于配置。
- 稀疏 MoLE 在显著减少 GPU 内存使用的同时,取得了与密集 MoE 相当的增益。
阅读本论文
在 Nubint 阅读器中打开原文,边读边就任意段落提问。
在 Nubint 中阅读本论文本解读由 AI 根据论文原文生成,引用前请核对原文。