
[论文解读] T2I-Adapter: Learning Adapters to Dig out More Controllable Ability for Text-to-Image Diffusion Models
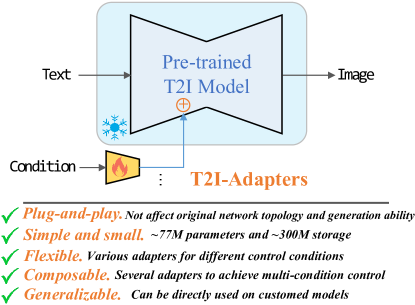
论文提出 T2I-Adapters,这是将外部控制信号与预训练的文本到图像扩散模型对齐的轻量级模块,从而实现更细粒度的控制而无需对基础模型进行再训练。
The incredible generative ability of large-scale text-to-image (T2I) models has demonstrated strong power of learning complex structures and meaningful semantics. However, relying solely on text prompts cannot fully take advantage of the knowledge learned by the model, especially when flexible and accurate controlling (e.g., color and structure) is needed. In this paper, we aim to ``dig out" the capabilities that T2I models have implicitly learned, and then explicitly use them to control the generation more granularly. Specifically, we propose to learn simple and lightweight T2I-Adapters to align internal knowledge in T2I models with external control signals, while freezing the original large T2I models. In this way, we can train various adapters according to different conditions, achieving rich control and editing effects in the color and structure of the generation results. Further, the proposed T2I-Adapters have attractive properties of practical value, such as composability and generalization ability. Extensive experiments demonstrate that our T2I-Adapter has promising generation quality and a wide range of applications.
研究动机与目标
- 证明小型适配器能够揭示并利用 T2I 模型的内部知识以提升可控性。
- 实现灵活、可组合、可泛化的控制信号(颜色、结构)且不重新训练基础扩散模型。
- 展示适配器能够在低数据量和低计算条件下训练,并以即插即用的方式嵌入。
提出的方法
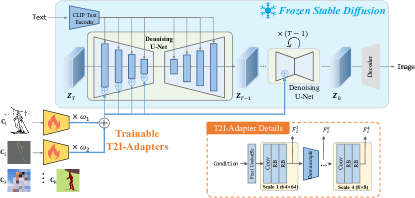
- 引入具备多尺度特征提取能力的轻量级 T2I-Adapter 架构,将条件特征注入 SD UNet 的编码器。
- 在冻结 Stable Diffusion 模型的前提下训练适配器,优化使适配器引导与扩散去噪对齐的损失(L_AD)。
- 通过可调权重(Eq. 5)将多种条件控制进行组合,支持多条件控制。
- 在训练时使用非均匀(立方)时间步采样,以强调在早期推理阶段指引最为重要的情形。
- 展示与各种控制信号兼容性(草图、分割、深度、关键姿态)以及通过空间色彩图实现的色彩调色板。
实验结果
研究问题
- RQ1轻量级适配器是否能够将外部控制信号与预训练 T2I 扩散模型的内部知识对齐,从而实现更细的控制?
- RQ2适配器是否能够实现可组合、多条件和可泛化的控制,而不修改原始扩散模型?
- RQ3适配器放置位置和训练策略对生成质量和可控性有何影响?
主要发现
- 适配器在不改变基础模型的生成能力的前提下实现可控引导。
- 与基线相比,在 COCO 验证集上该方法获得与之竞争或更优的 FID/CLIP 得分。
- 多条件适配器可通过组合实现联动控制(如深度 + 关键姿态、草图 + 颜色)。
- 适配器在 SD 版本(SD-v1.4 到 SD-v1.5)及从相同基底微调的自定义模型上具有良好泛化。
- 使用立方时间步采样训练可增强颜色与结构的引导效果。
- 微型适配器变体在参数量显著减少的同时仍能保持有效控制。
阅读本论文
在 Nubint 阅读器中打开原文,边读边就任意段落提问。
在 Nubint 中阅读本论文本解读由 AI 根据论文原文生成,引用前请核对原文。