
[論文レビュー] Composer: Creative and Controllable Image Synthesis with Composable Conditions
Composer は、画像を柔軟な表現に分解し、推論時に複数のユーザー選択可能な条件でそれらを再構成する構成型拡散フレームワークを導入します。高度に制御可能な画像合成と操作を実現します。再訓練なしで、タスク全般で高品質を達成します。
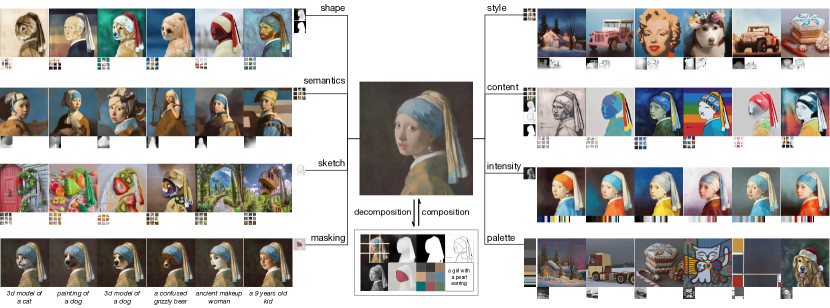
Recent large-scale generative models learned on big data are capable of synthesizing incredible images yet suffer from limited controllability. This work offers a new generation paradigm that allows flexible control of the output image, such as spatial layout and palette, while maintaining the synthesis quality and model creativity. With compositionality as the core idea, we first decompose an image into representative factors, and then train a diffusion model with all these factors as the conditions to recompose the input. At the inference stage, the rich intermediate representations work as composable elements, leading to a huge design space (i.e., exponentially proportional to the number of decomposed factors) for customizable content creation. It is noteworthy that our approach, which we call Composer, supports various levels of conditions, such as text description as the global information, depth map and sketch as the local guidance, color histogram for low-level details, etc. Besides improving controllability, we confirm that Composer serves as a general framework and facilitates a wide range of classical generative tasks without retraining. Code and models will be made available.
研究の動機と目的
- 条件間の構成性が画像合成の制御可能な設計空間を拡張することを実証する。
- 分解–構成パイプラインを備えた多条件拡散モデルを開発する。
- 再訓練なしで、テキストから画像、スタイル転送、ポーズ転送など多様なタスクをサポートすることを示す。
- 領域制御編集と堅牢な高解像度アップサンプリングのメカニズムを提供する。
提案手法
- 訓練中にオンザフライで抽出される、キャプション、意味情報/スタイル、カラーヒストグラム、スケッチ、インスタンス、デプスマップ、強度、マスキングの8つの表現に分解する。
- これらの表現のサブセットから画像を再構成するよう、UNet バックボーンを用いた多条件拡散モデルを学習する。
- 高レベルの表現にはグローバル条件付けを、空間的に変化する表現には局所的条件付けを用い、加法埋め込みとクロスアテンションガイダンスを組み合わせる。
- 分類器なしガイダンスと双方向ガイダンスを用い、柔軟な操作と分離した編集を可能にする。
- 生成された64x64画像を256x256へ、さらに1024x1024へ、2つの無条件拡散アップサンプリングモデルを用いてアップサンプリングする。
- キャプションを画像埋め込みへ射影する事前モデルを任意で用い、各条件ごとのドロップアウトを含む学習戦略を採用して、多様な条件の組み合わせからの学習を促進する。
実験結果
リサーチクエスチョン
- RQ1従来の単一条件モデルを超えて、構成的条件付けは画像合成の制御空間を拡張できるのか?
- RQ2再訓練なしで、さまざまな、潜在的に互換性のない表現から画像を再構成・操作するにはどうすればよいか?
- RQ3異なる条件モダリティ(グローバル対ローカル)が生成品質と制御性に与える影響はどのようなものか?
- RQ4このフレームワークは、カラー化、スタイル転送、翻訳、編集といった従来の生成タスクを1つのモデル内で再構成できるか?
主な発見
- Composer は、条件としてキャプションのみを使用した場合、COCO で zero-shot FID 9.2、CLIP スコア 0.28 という競争力のあるテキストから画像への品質を達成する。
- 本手法は、スケッチ、デプスマップ、カラー パレットによる再構成を含む、再訓練なしで広範なタスクと操作を可能にする。
- マスキング条件を用いることで領域特異的な編集が可能で、編集をユーザー定義の領域に制限する。
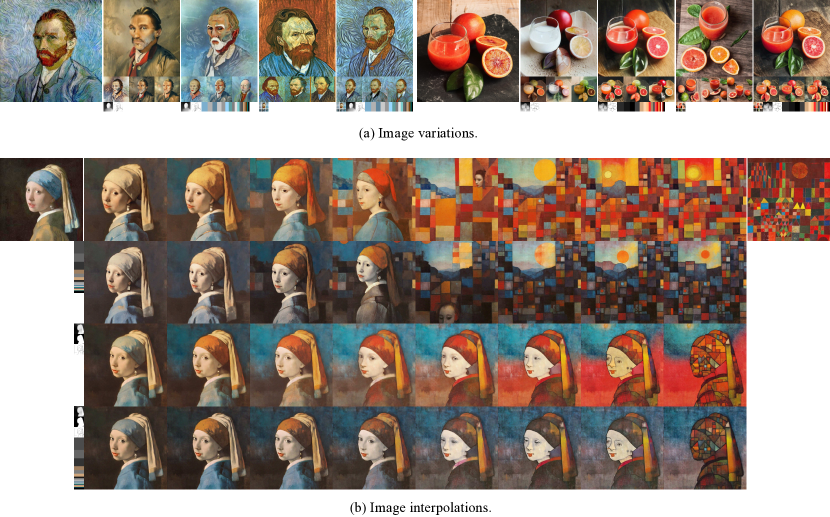
- グローバル表現をトラバーサルまたは選択的に組み合わせることで、補間とバリエーションを実現し、制御可能な多くの方向を生み出す。
- ドロップアウトによる複数条件の結合による共同訓練は、多様な条件の組み合わせからの学習を可能にし、アップサンプリングモデルは高解像度出力を提供する(最大 1024x1024)。
- このアプローチは、従来の生成タスクと新規の構成的シナリオの両方で高い制御性と柔軟性を達成する。
この論文を読む
Nubintのビューアで原文を開き、読みながら気になる箇所をすぐに質問できます。
Nubintでこの論文を読むこのレビューはAIが論文の原文をもとに作成しました。引用する前に原文をご確認ください。