
[논문 리뷰] CMATH: Can Your Language Model Pass Chinese Elementary School Math Test?
CMATH는 1.7k 아이템 중국 초등 수학 단어 문제 데이터셋을 도입하고 GPT-4가 모든 학년에 걸쳐 60% 이상을 일관되게 점수하는 유일한 평가 모델이며, GPT-4는 또한 방해자에 대해 견고함을 보인다.
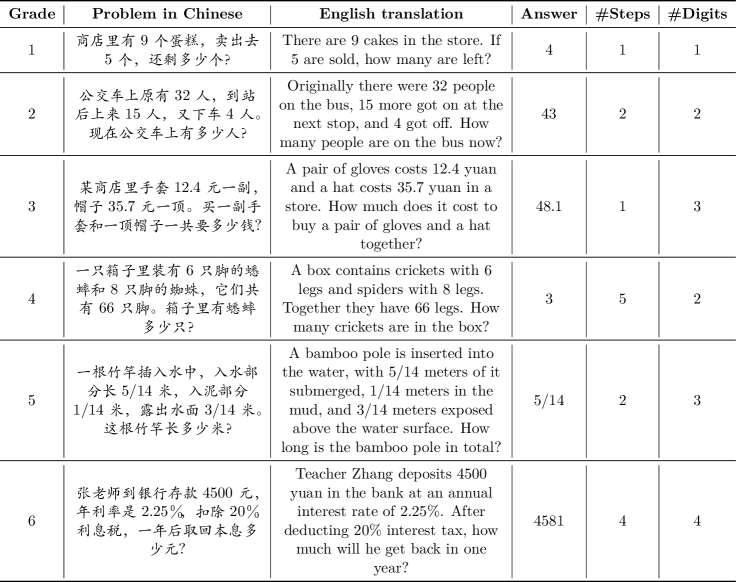
We present the Chinese Elementary School Math Word Problems (CMATH) dataset, comprising 1.7k elementary school-level math word problems with detailed annotations, source from actual Chinese workbooks and exams. This dataset aims to provide a benchmark tool for assessing the following question: to what grade level of elementary school math do the abilities of popular large language models (LLMs) correspond? We evaluate a variety of popular LLMs, including both commercial and open-source options, and discover that only GPT-4 achieves success (accuracy $\geq$ 60\%) across all six elementary school grades, while other models falter at different grade levels. Furthermore, we assess the robustness of several top-performing LLMs by augmenting the original problems in the CMATH dataset with distracting information. Our findings reveal that GPT-4 is able to maintains robustness, while other model fail. We anticipate that our study will expose limitations in LLMs' arithmetic and reasoning capabilities, and promote their ongoing development and advancement.
연구 동기 및 목표
- 실제 소스에서 세밀한 학년 주석이 달린 중국 초등 수학 단어 문제 데이터셋을 생성한다.
- CMATH 문제를 여섯 학년에 걸쳐 제로샷 해결에 대해 인기 있는 LLM들을 평가한다.
- 문제의 난이도(자릿수와 추론 단계)가 모델 성능에 어떤 영향을 주는지 분석한다.
- 상위 모델의 문제 진술에 있는 방해 정보에 대한 견고성을 평가한다.
- 초등 수학 추론에서 모델 능력에 대한 직관적이고 인간 중심의 해석을 제공한다.
제안 방법
- CMATH를 학년별로 주석된 1,700개 문제, 정답 유형, 추론 단계 및 숫자 개수로 구성한다.
- API 접근 가능한 모델과 오픈 모델 LLM들(GPT-4, ChatGPT, MOSS, Ziya-LLaMA, 중국어-알파카 계열, RWKV, Baichuan, ChatGLM)을 제로샷 모드로 평가한다.
- GROUND-TRUTH의 숫자와 비교하기 위해 모델 출력에서 정규식으로 자동 숫자 추출을 수행한다.
- 학년, 추론 단계 및 숫자 복잡성의 함수로써 성능을 분석한다.
- 방해자 데이터셋을 만들어 문제 서술에 단일 숫자 방해자를 추가하고 견고성을 테스트한 뒤 성능 저하를 측정한다.]
실험 결과
연구 질문
- RQ1CMATH에서 평가될 때 인기 있는 LLM의 수학 단어 문제 해결 능력이 어떤 초등 학년에 해당하는가?
- RQ2문제의 난이도(자릿수와 추론 단계)가 학년별로 모델 정확도에 어떤 영향을 미치는가?
- RQ3상위 모델들은 수학 단어 문제에 삽입된 방해 정보에 견고한가?
- RQ4방해자에 직면했을 때 어떤 모델이 정확도와 견고성을 가장 잘 유지하는가?
주요 결과
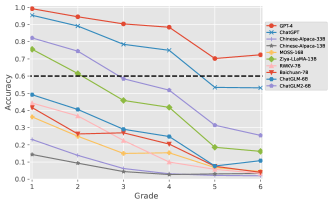
- GPT-4는 여섯 학년 모두에서 정확도가 60% 이상인 유일한 모델이다.
- ChatGPT는 1–4학년에서 성공하지만 5–6학년에서 실패한다.
- 대부분의 오픈 소스/중국어 중심 LLM은 일부 제한된 사례를 제외하고 모든 학년에서 실패한다.
- 학년이 올라갈수록, 추론 단계 또는 숫자가 증가할수록 모델 성능이 저하되며, 추론 단계가 산술 복잡성보다 더 큰 영향을 미친다.
- GPT-4는 방해자에 견고하게 남아 있는 반면, 다른 모델은 현저한 저하를 보인다.
- 방해자 실험에서 ChatGPT는 쉽게 오도되지만 GPT-4는 관련 정보에 집중을 유지한다.
이 논문 읽기
누빈트 뷰어에서 원문을 열고, 읽으면서 궁금한 곳을 바로 물어보세요.
누빈트에서 이 논문 읽기이 리뷰는 AI가 논문 원문을 바탕으로 만들었습니다. 인용하기 전에 원문을 확인해 주세요.