
[논문 리뷰] Composer: Creative and Controllable Image Synthesis with Composable Conditions
Composer는 이미지를 유연한 표현으로 분해하고 추론 시 다수의 사용자가 선택 가능한 조건으로 재구성하는 구성적 확산 프레임워크를 도입하여 높은 제어 가능한 이미지 합성 및 조작을 구현합니다. 재훈련 없이도 다양한 작업에서 높은 품질을 달성합니다.
Recent large-scale generative models learned on big data are capable of synthesizing incredible images yet suffer from limited controllability. This work offers a new generation paradigm that allows flexible control of the output image, such as spatial layout and palette, while maintaining the synthesis quality and model creativity. With compositionality as the core idea, we first decompose an image into representative factors, and then train a diffusion model with all these factors as the conditions to recompose the input. At the inference stage, the rich intermediate representations work as composable elements, leading to a huge design space (i.e., exponentially proportional to the number of decomposed factors) for customizable content creation. It is noteworthy that our approach, which we call Composer, supports various levels of conditions, such as text description as the global information, depth map and sketch as the local guidance, color histogram for low-level details, etc. Besides improving controllability, we confirm that Composer serves as a general framework and facilitates a wide range of classical generative tasks without retraining. Code and models will be made available.
연구 동기 및 목표
- 조건 간 구성이 이미지 합성의 제어 가능한 설계 공간을 확장한다는 것을 입증한다.
- 분해-구성 파이프라인을 갖춘 다중 조건 확산 모델을 개발한다.
- 재훈련 없이 텍스트-이미지, 스타일 전이, 포즈 전이 등 다양한 작업을 프레임워크가 지원함을 보인다.
- 영역 기반의 제어 편집 및 강건한 고해상도 업샘플링을 위한 메커니즘을 제공한다.
제안 방법
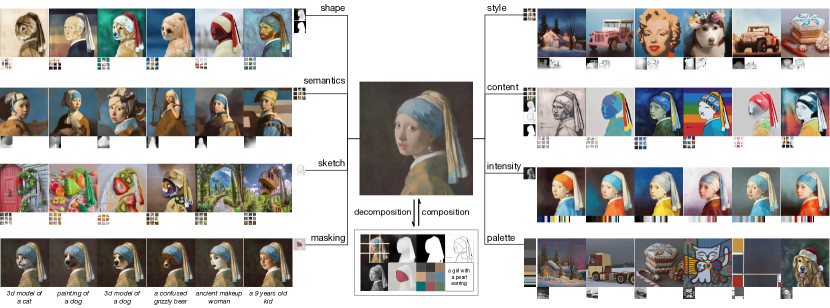
- 학습 중 실시간으로 추출되는 여덟 가지 표현(캡션, 의미/스타일, 색상 히스토그램, 스케치, 인스턴스, 깊이 맵, 강도, 마스킹)으로 각 이미지를 분해한다.
- 이 표현들 중 일부의 부분집합으로 이미지를 재구성하도록 다중 조건 확산 모델(UNet 백본)을 학습시킨다.
- 고수준 표현에는 글로벌 컨디셔닝을, 공간적으로 변하는 표현에는 로컬라이즈드 컨디셔닝을 사용하며, 가산 임베딩과 크로스-어텐션 가이던스를 포함한다.
- 더 유연한 조작과 해리된 편집을 가능하게 하려 classifier-free 및 양방향 가이던스를 적용한다.
- 생성된 64x64 이미지를 256x256으로, 그리고 1024x1024로 두 개의 무조건적 확산 업샘플링 모델을 사용하여 업샘플링한다.
- 캡션을 이미지 임베딩으로 투영하는 프라이어 모델을 선택적으로 사용하고, 조건별 드롭아웃이 적용된 학습 전략으로 다양한 조건 조합에서 학습을 촉진한다.
실험 결과
연구 질문
- RQ1전통적인 단일 조건 모델을 넘어 조건 구성 conditioning이 제어 가능한 설계 공간을 확장하는가?
- RQ2상이하고 호환되지 않을 수 있는 다양한 표현으로부터 이미지를 재구성하고 조작하는 방법은 재훈련 없이 가능한가?
- RQ3전역 대 로컬의 서로 다른 컨디셔닝 모달리티가 생성 품질과 제어 가능성에 어떤 영향을 미치는가?
- RQ4이 프레임워크가 전통적 생성 작업(색상화, 스타일 전이, 변환, 편집)을 하나의 모델 내에서 재구성할 수 있는가?
주요 결과
- Composer는 조건으로 캡션만을 사용할 때 COCO에서 0샷 FID 9.2, CLIP 점수 0.28로 텍스트-이미지 품질에서 경쟁력 있는 성능을 달성한다.
- 이 방법은 스케치, 깊이 맵, 색상 팔레트 등을 통해 재구성하는 것을 포함하여 재훈련 없이도 광범위한 작업과 조작을 가능하게 한다.
- 마스킹 조건을 사용하여 영역별 편집이 가능하여 사용자가 정의한 영역에 편집이 국한된다.
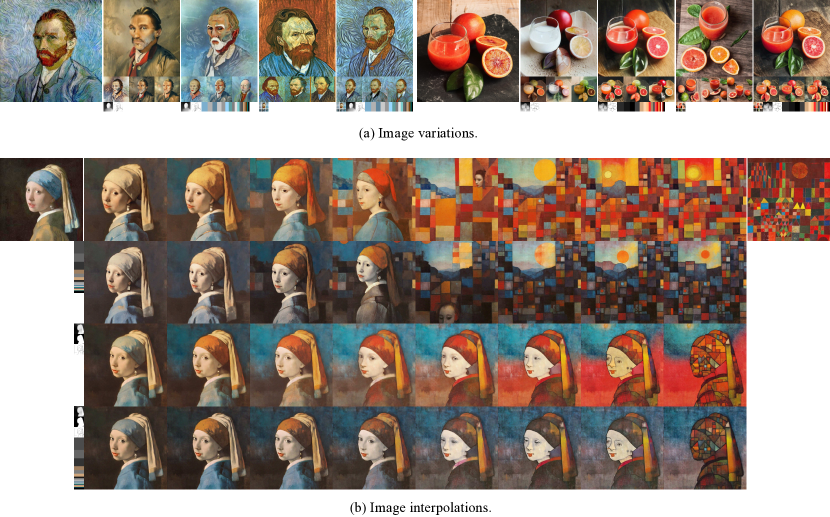
- 전역 표현을 순회하거나 선택적으로 결합하여 보간 및 변형을 달성할 수 있으며, 많은 제어 가능한 방향을 제공한다.
- 드롭아웃을 통한 다중 조건의 결합으로 공동 학습이 가능하고, 업샘플링 모델은 최대 1024x1024의 고해상도 출력을 제공한다.
- 이 접근 방식은 전통적 생성 작업과 새로운 구성적 시나리오 전반에서 높은 제어성과 유연성을 달성한다.
이 논문 읽기
누빈트 뷰어에서 원문을 열고, 읽으면서 궁금한 곳을 바로 물어보세요.
누빈트에서 이 논문 읽기이 리뷰는 AI가 논문 원문을 바탕으로 만들었습니다. 인용하기 전에 원문을 확인해 주세요.