
[논문 리뷰] Humanoid-Gym: Reinforcement Learning for Humanoid Robot with Zero-Shot Sim2Real Transfer
Humanoid-Gym은 Nvidia Isaac Gym을 기반으로 휴머노이드 보행 정책을 학습하고 제로샷 시뮬레이션-현실 전송을 가능하게 하는 오픈 소스 RL 프레임워크로, MuJoCo에서의 시뮬레이션-시뮬레이션 검증과 두 대의 RobotEra 휴머노이드(XBot-S 및 XBot-L)에 대한 실제 검증을 수행합니다.
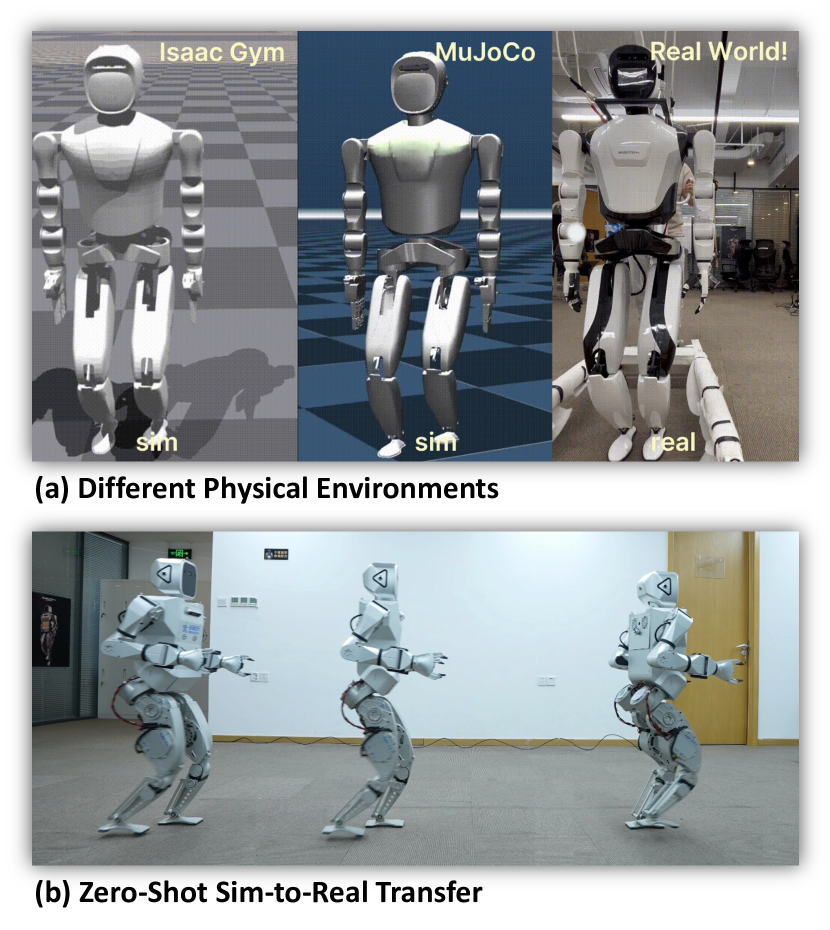
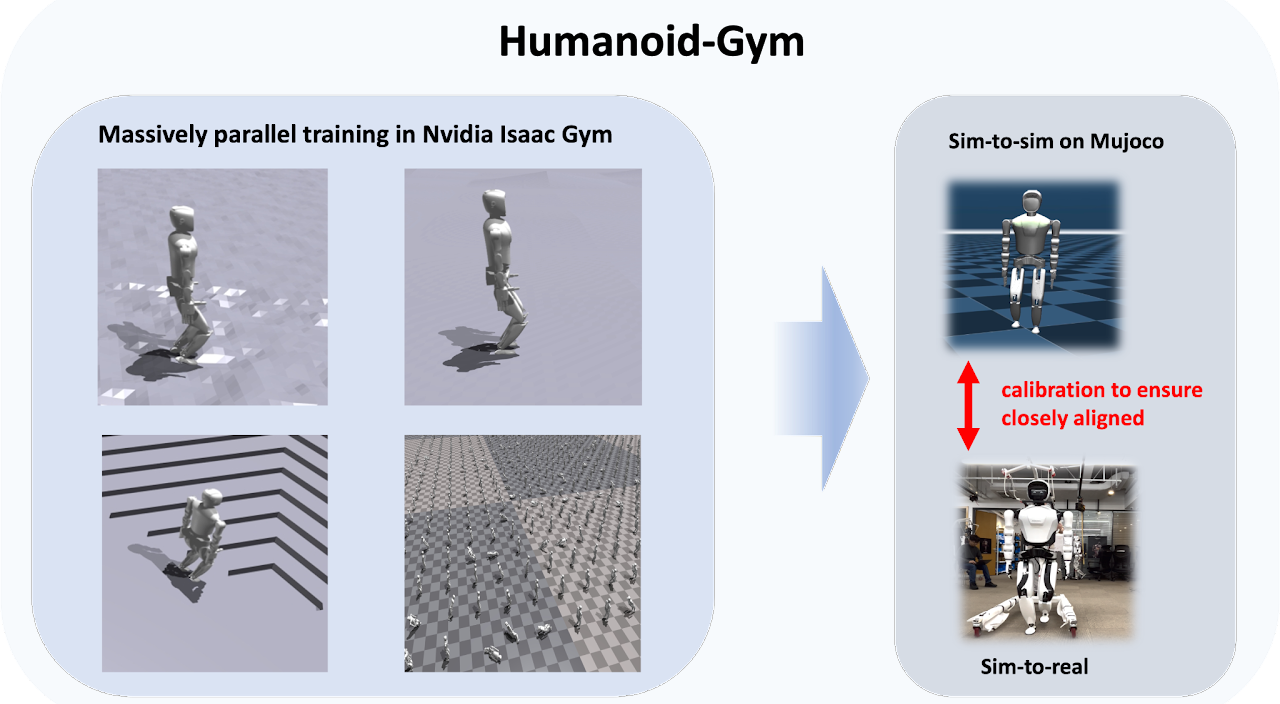
Humanoid-Gym is an easy-to-use reinforcement learning (RL) framework based on Nvidia Isaac Gym, designed to train locomotion skills for humanoid robots, emphasizing zero-shot transfer from simulation to the real-world environment. Humanoid-Gym also integrates a sim-to-sim framework from Isaac Gym to Mujoco that allows users to verify the trained policies in different physical simulations to ensure the robustness and generalization of the policies. This framework is verified by RobotEra's XBot-S (1.2-meter tall humanoid robot) and XBot-L (1.65-meter tall humanoid robot) in a real-world environment with zero-shot sim-to-real transfer. The project website and source code can be found at: https://sites.google.com/view/humanoid-gym/.
연구 동기 및 목표
- 크기가 다른 휴머노이드 로봇의 시뮬레이션에서 실제 세계로의 제로샷 전송을 가능하게 한다.
- 다양한 역학 특성에 걸친 정책을 테스트하기 위한 시뮬레이션-시뮬레이션 검증 경로를 제공한다.
- 휴머노이드를 위한 특화 보상과 도메인 무작위화를 갖춘 접근 가능한 오픈소스 RL 라이브러리를 제공한다.
- MuJoCo 기반 검증을 통해 물리적 로봇 없이도 견고한 정책 검증을 촉진한다.
제안 방법
- 관측치를 행동으로 매핑하고 기대 반환을 극대화하는 정책 π(a|o)으로 작용하는 POMDP에서 M = <S,A,T,O,R,γ> 형식의 강화학습 모델을 사용한다.
- 학습 중 비대칭 액터-크리틱 및 특권 정보를 보강하여 Proximal Policy Optimization (PPO) 손실로 최적화한다.
- 참고 사인파 보행과 발 접촉을 위한 주기적 자세 마스크를 포함한 고주파 제어 루프를 설계한다(정책이 100 Hz, 내부 PD 제어기가 1000 Hz).
- 시계 신호, 명령, 관절 상태, 각 속도, 기본 포즈 및 특권 관찰을 포함하는 풍부한 관찰 공간을 정의하여 로버스트한 고유감지(Proprioceptive sensing)를 가능하게 한다.
- 시뮬레이션-현실 간 격차를 줄이기 위해 관절 위치/속도, 지연, 마찰, 모터 강도, 페이로드 및 기타 역학에 걸친 도메인 무작위화를 적용한다.
- Nvidia Isaac Gym에서 광범위하게 학습하고 시뮬레이션-시뮬레이션(MuJoCo)을 통해 검증한 후 시뮬레이션-현실 전송을 시도한다.
- MuJoCo 역학을 실제 액추에이터 및 팔다리 거동과 거의 일치하도록 보정하고, 다리의 스윙 사인파와 관절 위상도 비교로 검증한다.
실험 결과
연구 질문
- RQ1크기가 다른 휴머노이드 간에 휴먼노이드 보행의 제로샷 시뮬레이션-현실 전송이 달성될 수 있는가?
- RQ2MuJoCo에서의 시뮬레이션-시뮬레이션 검증이 실제 성능과 상관관계가 있는 신뢰할 수 있는 로버스트니스 체크를 제공하는가?
- RQ3휴머노이드의 시뮬레이션-현실 격차를 줄이는 데 도메인 무작위화와 보상 설계가 얼마나 효과적인가?
- RQ4보정 후 MuJoCo 역학이 실제 휴머노이드 보행을 얼마나 정확하게 재현할 수 있는가?
- RQ5물리적 로봇에 접근하지 못하는 연구자들을 위한 Humanoid-Gym의 오픈소스 배포에 대한 실용적 고려사항은 무엇인가?
주요 결과
- 시뮬레이션에서 학습된 정책으로 실제 세계의 휴먼노이드(XBot-S 및 XBot-L)로의 제로샷 전송이 시연되었다.
- 보정된 MuJoCo 역학이 다리 스윙 궤도 및 관절 위상 도표를 실제 데이터와 근접하게 만들어 시뮬레이션-현실 정확도 향상을 시사한다.
- Humanoid-Gym은 다른 환경 역학에 걸친 시뮬레이션-시뮬레이션 검증을 가능하게 하여 정책의 견고성과 일반화를 지원한다.
- 도메인 무작위화와 특수 보상 설계로 시뮬레이션-현실 전송 시나리오에서 평지와 울퉁불퉁한 지형 모두에서 안정적인 보행을 가능하게 한다.
- 프레임워크는 오픈소스로 구현되었으며 Isaac Gym 학습부터 MuJoCo 검증 및 실제 배치까지의 완전한 파이프라인을 포함한다.
이 논문 읽기
누빈트 뷰어에서 원문을 열고, 읽으면서 궁금한 곳을 바로 물어보세요.
누빈트에서 이 논문 읽기이 리뷰는 AI가 논문 원문을 바탕으로 만들었습니다. 인용하기 전에 원문을 확인해 주세요.